
Hosted clinical trial harmonization for academic and nonprofit research
Preparing trial data for secondary research takes time. Each sponsor delivers its own table layouts, codes, units, and subject IDs, so every trial has to be brought to a common standard before a cross-trial cohort can be built, often taking months of data management time. Please see our clinical trial case study to see the steps involved in data harmonization.
A2K was developed in collaboration with the nonprofit Clinical Research Data Sharing Alliance (CRDSA). As part of that collaboration, A2K has committed to preferential pricing for academic and nonprofit organizations on its clinical trial harmonization services.
The Research Program is available only to qualified academic and nonprofit organizations. Pricing is a one-time setup fee per organization plus $500 per trial processed, with no volume commitment.
Research Program overview
Datasets
The hosted program accepts clinical trial datasets, including trials that do not follow SDTM format. The hosted service accepts only anonymized datasets. Any data that concerns individuals must be anonymized before it is uploaded, and identified protected health information is out of scope.
Scope
The Research Program uses A2K's standard specification pack for clinical trial data. It harmonizes trials to the CDISC SDTM standard across eight data domains: demographics (DM), adverse events (AE), concomitant medications (CM), laboratory results (LB), vital signs (VS), medical history (MH), disposition (DS), and exposure (EX). These are the domains most frequently used for pooling and cohort development. Other uploaded data domains are passed through and returned as part of your download package.
Run results
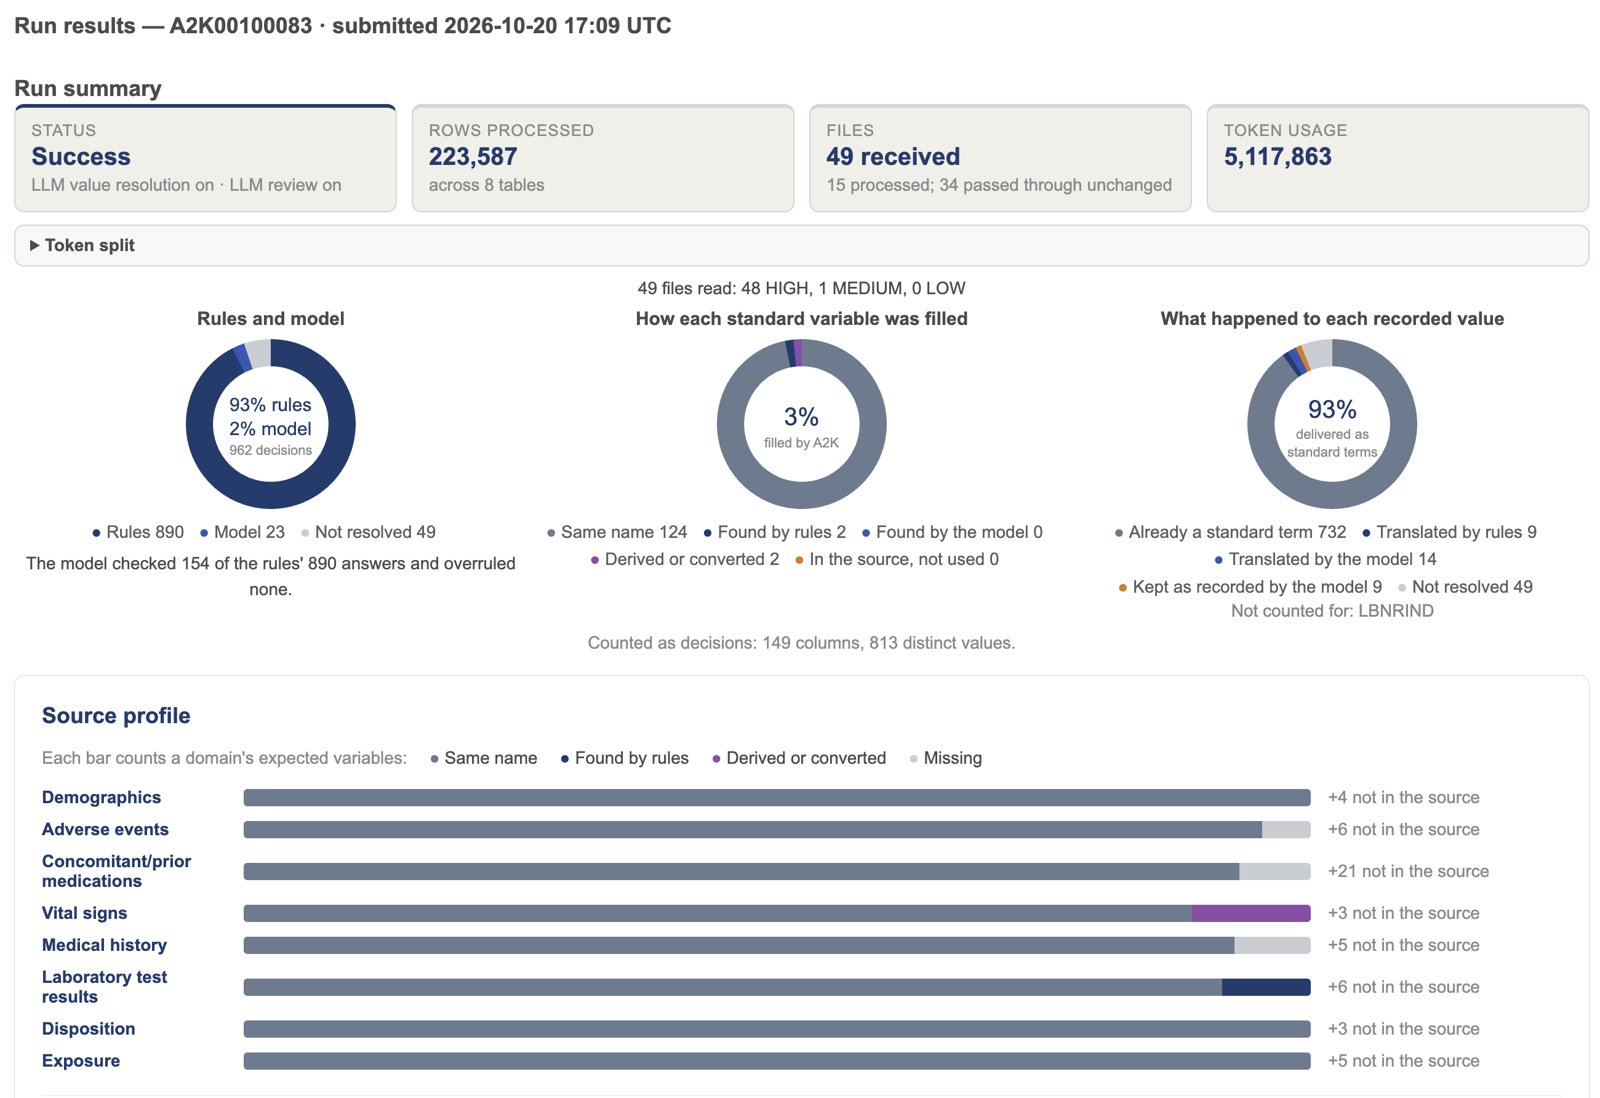
- 1
Run summary: Status, rows processed, files received, and model use for the run.
- 2
How each decision was made: The share settled by standard rules and by the AI model, how each standard variable was filled, and what happened to each recorded value.
- 3
What needs your review: Decisions that may need a second look, such as values outside the expected set, are listed for a reviewer before the data is used.
- 4
Source data quality: For each domain, A2K lists the expected variables the source is missing and its other limits, so users know which questions the data cannot answer.
Download package
One package per run, organized for analysis and audit.
For each source table
- Harmonized data
- standard tables, with sponsor columns that have no standard variable carried as recorded
- Value-level provenance
- the original source value, the result, and how it was produced (standard rule, AI model, or derivation)
- QC report
- findings on the harmonized output
- Define-XML
- standard machine-readable metadata
- Mapping report
- a readable account of every variable column
- Source data quality
- the completeness and other limits of each source table
Across the package
- Combined tables
- one table per data domain
- Review list
- decisions that warrant review
- Source profile
- what each domain's source contains and what it is missing
- Subject ID lookup
- the A2K ID beside each source's subject IDs, so end users can apply the A2K ID to data domains that were passed through without processing
- Manifest
- every file, with row counts and checksums
Data handling
Uploaded files and results are held on encrypted storage while a run is processed and downloaded, and are then deleted. A2K keeps no copy of your data and never uses it to train models.
Using the hosted service
Your team signs in to A2K's secure hosted service, uploads the source files for a trial, and downloads the harmonized results package when the run is finished.
Eligibility
The Research Program is available to academic and nonprofit organizations. Contact us to confirm eligibility and terms.
If your institution needs to apply your own specifications, explore other data types, or have A2K run inside your environment, see Enterprise →
To find out more about the Research Program, please email us at research at a2knowledge dot com.
The Research Program and Enterprise compared
| Enterprise | Research Program | |
|---|---|---|
| Who it is for | Any organization that needs its own specification pack or an in-environment deployment | Academic and nonprofit research institutions using A2K's standard pack |
| Where it runs | A2K's hosted service, your own cloud environment, or embedded in your own platform | A2K's secure hosted service |
| Data types | Any life sciences data type, with a specification pack built for it | Clinical trial data |
| Standard | Your data models, ontologies, and standards | CDISC SDTM, eight data domains |
| Specification pack | Built for your organization | A2K's standard pack, current version |
| AI model provider | A2K's provider, or your provider of choice when A2K runs in your environment | A2K's provider |
| Getting started | Scoping and deployment planning | Browser sign-in after onboarding |
| What you receive | The A2K download package | The A2K download package |