
About
From the founder
For the last decade, I've worked to make research data more accessible and more usable. During the COVID-19 pandemic, I led a team that built a platform in about six weeks to share clinical data across pharmaceutical sponsors and academic institutions. Senior leaders committed to sharing data, and the platform delivered access. What we learned afterward was that access alone doesn't make data ready for research. Pooling data from different sources is a heavy lift, and it often takes experienced teams months.
Software for data harmonization isn't new. Rules-based tools work well until something changes: a new source, a new data type, a revision to the standard. Each change means more code to close gaps, resolve ambiguity, and keep up with the sources, and that approach doesn't scale.
In late 2025, I started looking at how the latest advances in AI could address these problems reliably. Three requirements shaped A2K:
- Every decision has to be traceable. A2K uses large language models as components inside a governed pipeline and records how every value was produced, so nothing happens inside a black box.
- Standards have to be readable by machines. A data model or standard written for people has to be translated before an AI model can apply it consistently. A2K turns it into a specification pack that both the rules and the AI model work from.
- Data should stay where it is. Moving data across organizational boundaries brings legal and security work. A2K can run inside your own environment, so the protection comes from where the software runs.
A2K's development process
Design before code
Substantive changes start as written design memos and requirements. Each one is drafted, reviewed in a separate pass by a reviewer that did not write it, and approved by a person before any code is written. Getting requirements right is treated as an engineering control, because that is where mistakes cost least to fix.
Specifications and code kept apart
Specification work and engine development run as separate roles with separate inputs. Specifications and their test data are written to the data model or standard, never to the engine's current behavior, so testing exposes weaknesses in the engine instead of hiding them.
Automated gates
Every change runs through continuous integration: unit tests, static analysis, schema conformance checks, and regression against a synthetic dataset with a known answer key. A change that fails a gate does not merge, and every change is approved by a person before it merges.
Release checks
Before a build goes live, it must pass the full test suite, a regression check against a frozen baseline, and a check that the deployment image builds and starts. New builds are then validated by rerunning full synthetic datasets and comparing results before and after.
Periodic review
Beyond per-change checks, the codebase receives periodic end-to-end reviews for hygiene and design debt. Findings are logged and prioritized by their effect on the delivered output, and fixed as planned work.
Background
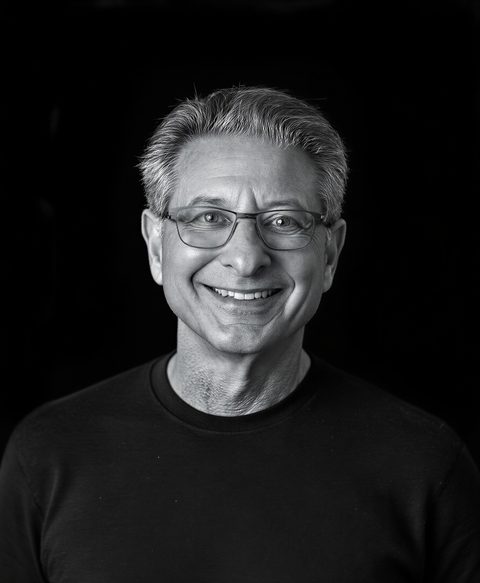
A2K was founded by Aaron Mann, its Chief Executive Officer. Aaron co-founded the Clinical Research Data Sharing Alliance (CRDSA) in 2021, a multi-stakeholder consortium whose standards and tools have been downloaded more than 27,000 times across 90+ countries. Before CRDSA, he led Roche's industry data-sharing collaborations and, as industry lead for TransCelerate BioPharma's data-sharing platform, drove the industry's COVID-19 patient-level data-sharing initiative. He has more than 25 years of experience across global enterprises, high-growth technology companies, and early-stage startups.
The A2K platform was developed in collaboration with CRDSA.
Contact
To ask about the Research Program, an Enterprise deployment, a partnership, or a demonstration, send us a message.